Fix loop and judge
An exec node's fix_loop repairs the node and measures it again until it
passes. This page is the loop's contract: when it opens, what runs in each
cycle, and how the judge's verdict is read. For why loops and caps work the
way they do, see Caps and budgets.
Keys
A fix_loop takes exactly one of tasks or steps. A node with a fix_loop
cannot be read_only.
| Key | Type | Default | Meaning |
|---|---|---|---|
tasks or steps | list | required, one of them | The repair. Runs as an ordered group, like a node's own steps. No task or step in it may take an on_failure. |
judge | mapping | none | One task of any kind, which may not take an on_failure. The shipped one is strict_judge. |
max_attempts | integer | from the layers below | The loop's attempt limit. Above 0. |
Limits
The loop's limits come from four layers. A later row replaces only the keys it sets, so the last row that sets a key wins. See policy.yaml.
| Layer | Attempts key | Wall-clock key |
|---|---|---|
1. policy.yaml's loops.<node>.fix_loop entry, else its default | attempts | wall_clock_s |
2. The node's policy | max_attempts | timeout_minutes |
| 3. The loop's own keys | max_attempts | none |
4. The work item's own policy (kraft item set-policy) | max_attempts | none |
When the loop opens
After the node's tasks run, Kraft reads every measuring task's findings and
records a findings_measured event. The
loop opens when either is true:
- a finding's severity is in
findings.loop_severitiesinpolicy.yaml(defaultcriticalandimportant); - a task failed without reporting any findings. Kraft writes one
criticalfinding for it, as a subprocess task describes.
Otherwise the node completes. Findings below the loop severities are kept and shown at the review gate.
A step that did not run in this measurement contributes nothing. When an earlier step fails, the steps after it do not run, and what they found the last time the node was measured is not read again.
A node with an on_failure handler recovers first: when its tasks fail, the
handler runs once, before the first cycle, and Kraft measures again. If that
leaves the node clean, the node completes and no findings_measured event is
recorded. If it does not, that measurement is recorded with cycle set to
-1, and the same rule decides whether the loop opens.
One cycle
Each cycle runs these checks in order. A stuck node is one whose escalation runs first, and then the item stops and waits for you.
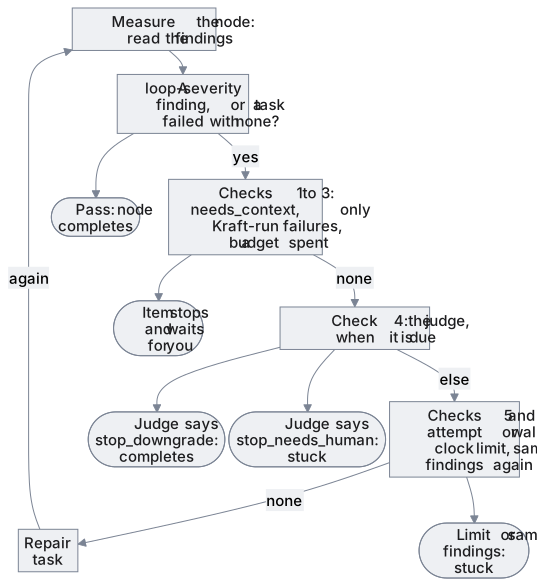
| # | Check | Outcome |
|---|---|---|
| 1 | A measuring task ended needs_context. | The item stops and waits for you, with its question. |
| 2 | Every failure came from a task Kraft runs itself (a builtin or forge task), and nothing else reported a finding. | The item stops and waits for you, because no worker commit can change the outcome. |
| 3 | A token or dollar budget is spent. | The item stops and waits for you. |
| 4 | The judge, when it is due. | continue goes ahead, stop_needs_human makes the node stuck, and stop_downgrade completes the node. See the verdicts. |
| 5 | The attempt count or wall clock is past its limit. | The node is stuck, with the reason <node>.fix_loop exhausted after N fix cycle(s). |
| 6 | After a repair, the same set of loop-severity findings came back, or one finding came back unchanged three cycles running. | The node is stuck, with a reason that starts stuck:. |
If nothing stopped the loop, Kraft records
fix_cycle_started, runs the repair, and
measures the whole node again from its first step.
Whether the repair spends the attempt depends on how it ended:
| Repair outcome | The attempt |
|---|---|
Ended done, or failed in an agent or subprocess task | Spent. |
Paused, rate limited, refused to start, or failed in a builtin or forge step | Given back, because the repair tried nothing. Kraft records fix_cycle_refunded instead of measuring again. |
When the repair ends, Kraft records
fix_cycle_finished with whether it
committed a change (committed), so the item's Recent list can say whether a
round changed anything.
The attempt count starts over when the node runs again on a new
pass: after a gate rejection that re-runs it, a
retry you ask for yourself, or a base-change restart. Kraft records the reset as
cap_counters_reset. A retry an
agent asks for keeps the count.
What a repair task is told
A repair task's own prompt is not used. Its harness profile, agent profile, model and skill
still are. Kraft writes its instruction instead:
- which tasks failed, or that a review reported findings;
- the loop-severity findings, each with its tag, a finding that was in the last
measurement marked
REPEAT; - the judge's reasoning, when the judge ran this cycle;
- once there are two rounds, every round so far, with any finding that was fixed and came back;
- the path of the previous attempt's result file and session summary.
The judge
The judge runs before every cycle except the first one after the node is entered. That first cycle repairs without a judge. The judge also does not run while a person's steer or a gate review is waiting to be delivered, because the steer already answers what the judge would rule on.
Its own prompt is not used either. Its instruction lists every round so far
with each finding's tag, the attempts used of the limit, and the seconds used
of the wall clock. It answers in its result file:
verdict, and its reasoning in concerns.
verdict | What happens |
|---|---|
continue | The cycle goes ahead. The repair task gets concerns as the judge's reasoning. |
stop_needs_human | The node is stuck with judge: and the reasoning. |
stop_downgrade | The node completes with the remaining findings unresolved, and concerns is the note you see at the review gate. Only when no task in the node failed outright; otherwise the cycle goes ahead. |
Kraft reads a verdict only from a judge that ended done or
done_with_concerns. Any other status, a missing verdict or an unknown one
counts as continue. A verdict never buys a cycle past the attempt limit or
the wall clock: check 5 runs after the judge. A loop with no judge always
continues. Each verdict is recorded as a
judge_verdict event.
Related
- Subprocess tasks: the finding Kraft writes for a failed command.
- Result file: how a judge writes its verdict.
- Caps and budgets: why loops and caps work this way.